Kandinsky 6.0 Video With Synced Audio
Synced Audio
An MIT-licensed open-source model family that generates video and its soundtrack together — dialogue, music, ambience and lip-sync in one pass.
Kandinsky 6.0 Video, released by Kandinsky Lab, ships in two sizes: a 29B-parameter Pro model and a 3B-parameter Lite model. Both produce 5-second clips with synchronized 44 kHz audio from either a text prompt (T2AV) or a still image (I2AV), and a built-in super-resolution stage lifts the result to Full HD. This page explains what the model does, what it takes to run it, and how it compares with the hosted audio-video models you can use on VO3 right now without a GPU.
Video Gallery
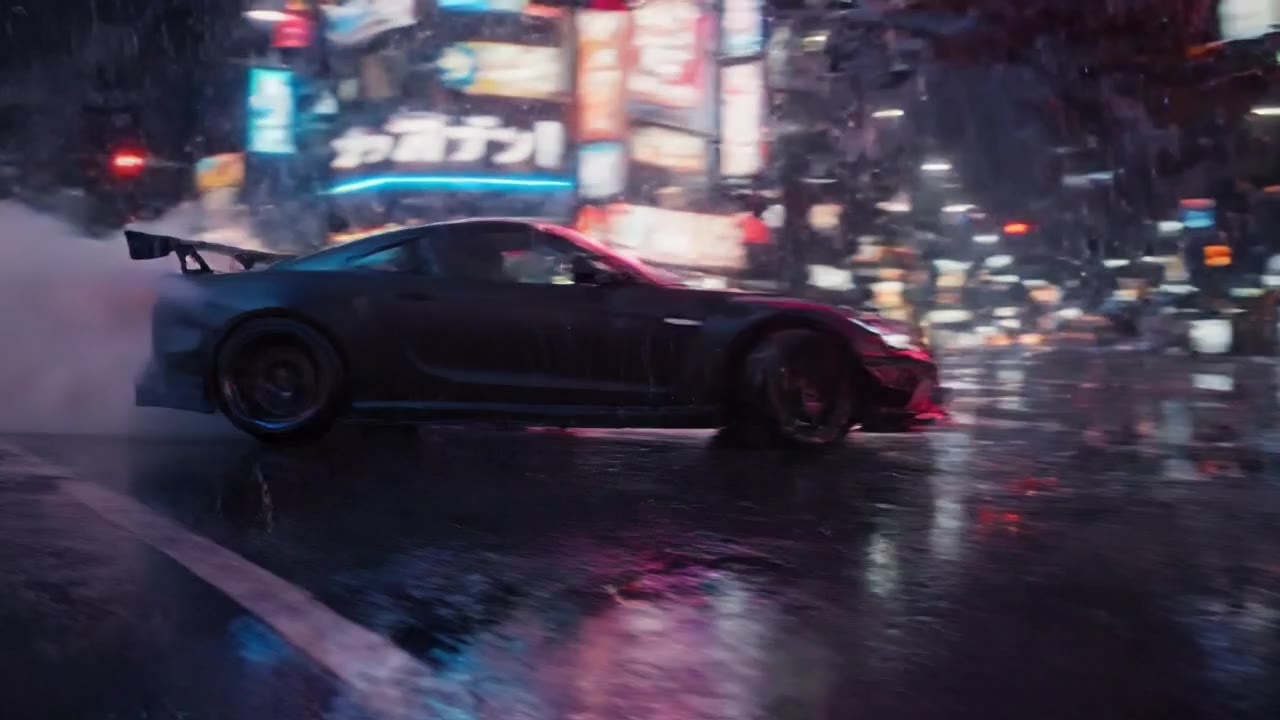
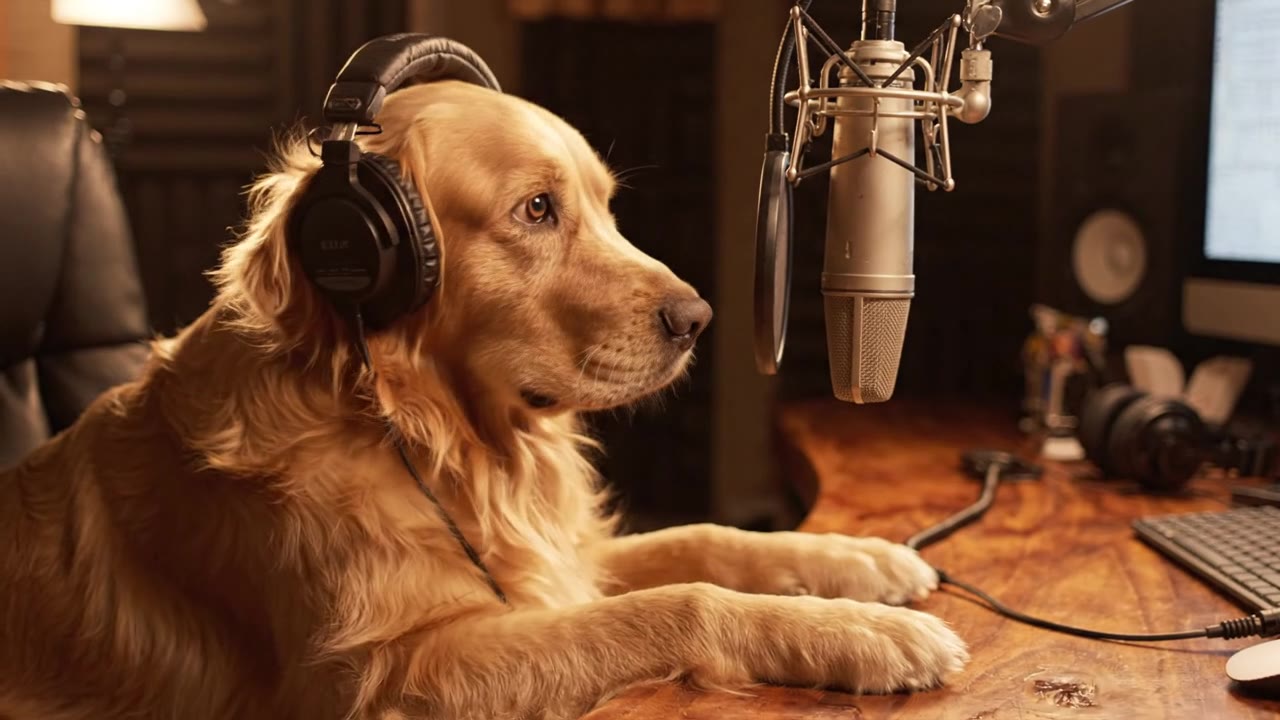
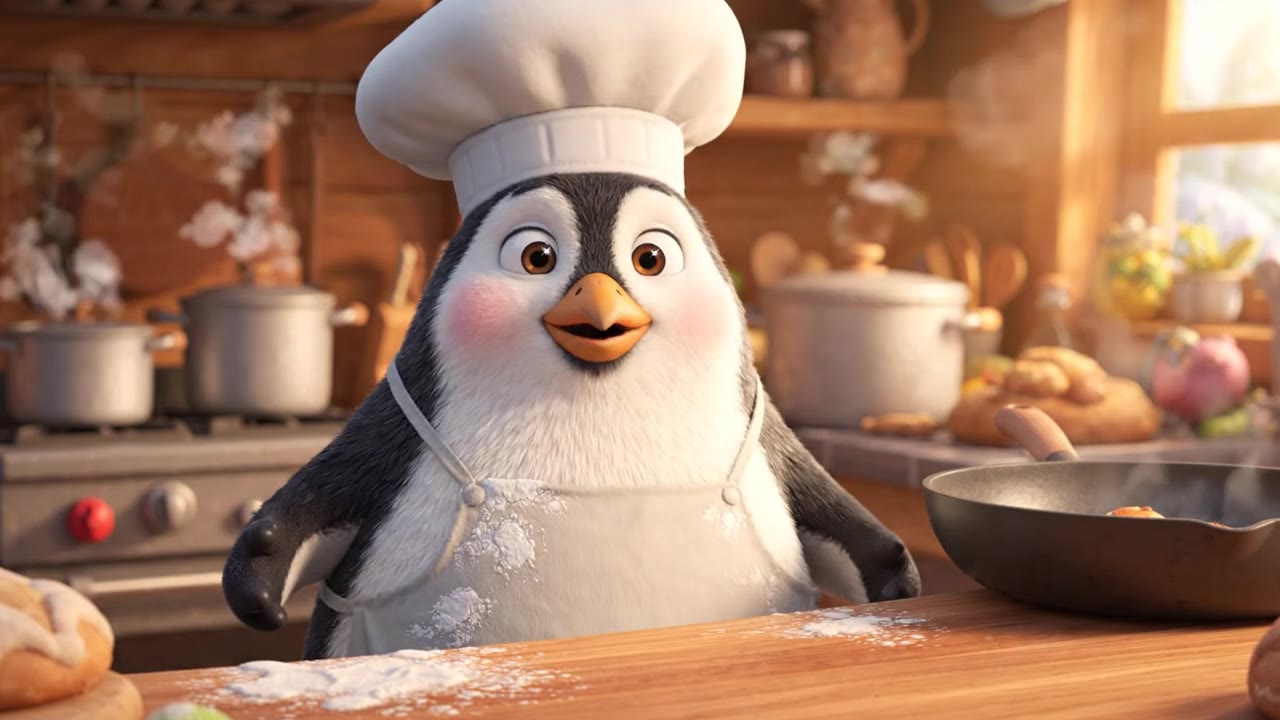
What Kandinsky 6.0 Video Brings
Video And Audio In One Pass
Most open-source video models output a silent clip that you then have to score by hand.
Kandinsky 6.0 Video generates the picture and its 44 kHz soundtrack jointly, so footsteps, dialogue, music and room ambience line up with the action instead of being dubbed on afterwards.
Native Lip-Sync
Because speech is produced alongside the frames, character mouth movements track the dialogue they are speaking.
That removes the usual second pass through a separate lip-sync tool for talking-head and spokesperson shots.
Two Model Sizes
Kandinsky 6.0 Video Pro runs 29 billion parameters for maximum fidelity,
while Kandinsky 6.0 Video Lite runs 3 billion for far lighter hardware. The Lite checkpoint is the realistic option if you are self-hosting on a single consumer card.
MIT License
Code and weights are published under the MIT license, so you can use the models commercially,
fine-tune them on your own footage and ship products built on top without negotiating a separate license.
Full HD Super-Resolution
The base generation runs at a lower internal resolution,
then a built-in super-resolution model upscales the output to 1920x1080. You get a deliverable-sized clip without bolting on a third-party upscaler.
Text And Image Driven
Both T2AV (text to audio-video) and I2AV (image to audio-video) modes are supported,
so you can start from a written prompt or animate a product photo, character sheet or storyboard frame you already have.
Dual-Stream CrossDiT Architecture
Audio and video are handled as two streams that attend to each other through a CrossDiT design
trained in multiple stages. That cross-attention is what keeps the two tracks locked together rather than merely adjacent.
Weights You Can Actually Host
The checkpoints live on Hugging Face and the inference code on GitHub,
which makes Kandinsky 6.0 Video a genuine option for teams with data-residency rules that rule out sending prompts to a third-party API.
How To Get Started
Decide: Self-Host Or Hosted
If you need the weights on your own hardware — air-gapped work, custom fine-tunes, research — pull Kandinsky 6.0 Video from Hugging Face. If you mainly need finished clips today, a hosted audio-video model skips the entire setup step.
Pick Pro Or Lite
For self-hosting, Lite at 3B is the checkpoint that fits a high-end consumer GPU. Pro at 29B is a datacenter-class model: plan for professional accelerators and meaningfully longer generation times per clip.
Write A Prompt That Describes Sound
With joint audio-video models, your prompt should specify what is heard as well as what is seen — the line of dialogue, the music bed, the ambience. Prompts written for silent models leave the audio track to chance.
Generate, Review, Iterate
Clips are 5 seconds, so plan sequences as a series of shots rather than one long take. Review the lip-sync and audio alignment first, since those are the hardest things to repair later in an edit.
Assemble And Deliver
Upscale to Full HD, then cut your shots together in any editor. Keep the generated audio as a separate stem where you can, so a composer or sound designer can still mix over it.
What Our Users Say
We benchmarked Kandinsky 6.0 Video Lite against our silent-model pipeline and the joint audio alone cut a full day of sound design out of each campaign. For client-facing work we still render on VO3 because the deadline math doesn't survive a GPU queue.
Our compliance team won't let prompts leave our infrastructure, so an MIT-licensed model we can host is the only path open to us. We run Lite internally for concept boards and it has taken storyboard turnaround from three days to about four hours.
I tested the 29B Pro checkpoint on rented accelerators for a music promo. The lip-sync is genuinely good, but at roughly $40 of compute per usable take I moved the client work to hosted models and kept Kandinsky for R&D.
As a team of two we don't have anyone to babysit CUDA drivers. We read up on Kandinsky 6.0, decided self-hosting wasn't our fight, and shipped 60 product clips last quarter on VO3 instead — about 70% under what our old freelance video budget was.
For a university research group the MIT license is the headline. We fine-tune Lite on archival footage for a media-studies project, something no commercial API would let us do, and publish the adapters alongside the paper.
Frequently Asked Questions
Ready to Get Started?
Join thousands of creators using our AI video platform to produce professional-quality content.